Video data infrastructure for physical AI, robotics, world models, VLAs and humanoids.

We capture, index, annotate and deliver the highest-quality egocentric video.

Left hand: The hand holds the dosing cup under the grinder spout, steadying it against the chute while the grounds fall in.Right hand: The hand reaches to the front of the grinder and rests against it beside the other hand, fingers loosely curled.
Dosing and weighing ground coffeeRight hand: Reach outLeft hand: Manipulate in hand
  1. Actions
  2. Captions
  3. Hand pose
  4. Raw clip

investors and partners

A curated Video Datalake that grows every month.

We're building toward millions of hours of diverse, high-quality video data.

Real work, everywhere.

Our own rigs record at real work sites: a head-mounted stereo pair and a wrist view, synced.
Filtered. Indexed. Growing.

Every clip passes QC and is indexed per hand, action and task before it joins the lake.

Last monthThis monthNext month

Ready to train robots.

Clips arrive in the shape robot learning needs.

The infrastructure layer.

We run the end-to-end system that enables efficient training cycles.

Capture

Our sites, our rigs.

Wearable rigs record video where the work happens, mounted at the head, wrist, chest, cap or neck. Also captured: raw IMU and camera calibration.

4-camera headset
Stereo headband
Wrist camera
Index

Every action, indexed per hand.

Each hand's actions become time-stamped segments, so the lake can be searched by action.

Explore
Left and right hand · action segmentsClip S8 · 06:54 → 07:19
L · GraspR · Grasp
Retrieve

Curate what's usable.

We query the lake for the video you need, then annotate it against your taxonomy.

# retrieve.py · illustrative
moments = lake.retrieve(
    venue="construction site",
    scenes=["rebar area",
            "formwork area"],
    skill_level="hard",
    where="both hands on the tool",
    exclude=["hand idle", "walking"],
)
moments.annotate(
    taxonomy="your_taxonomy.yaml")
# → rebar and formwork moments, labelled
Annotate

Dense captions, to the frame.

Each hand gets a caption for every segment, written against your taxonomy frame by frame.

Explore
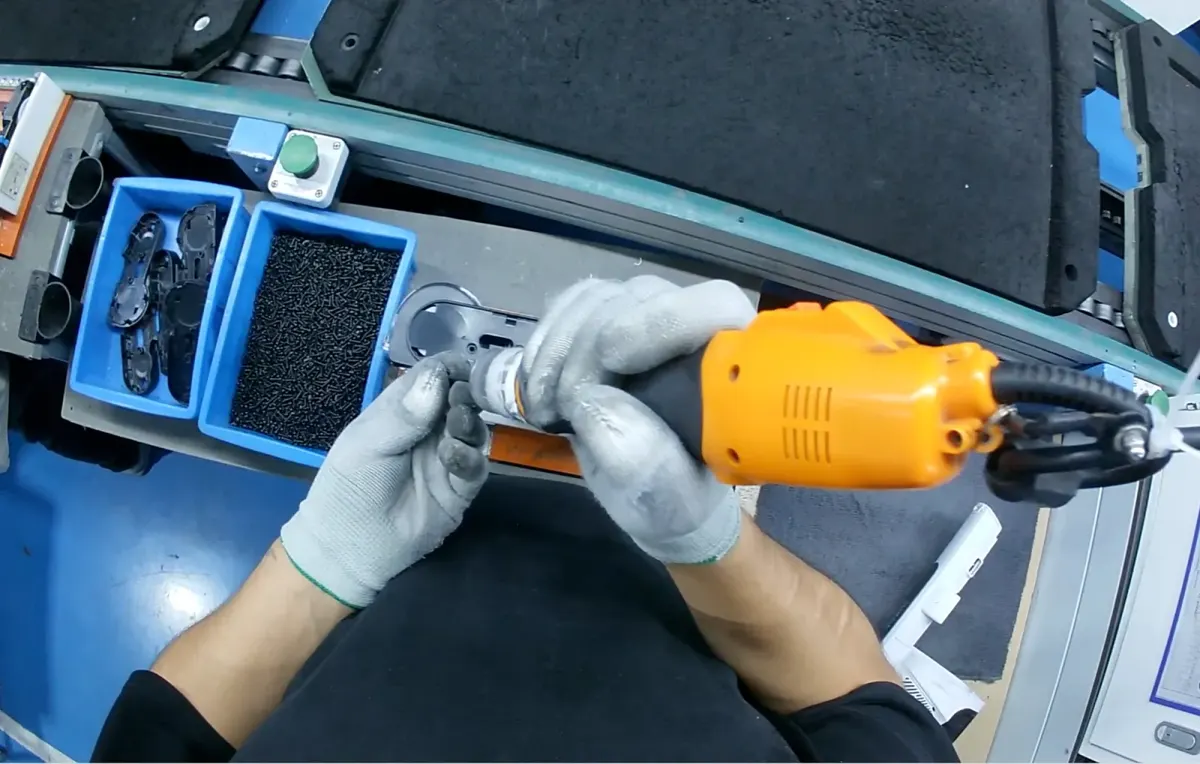
First-person view at an assembly station: gloved hands drive a screw into a black part with an orange electric screwdriver, bins of parts and screws beside them
07:00.043RightThe hand holds an item stationary in a pinch grip, then shifts slightly inward while adjusting its fingers around it.
07:01.376LeftThe hand holds the item stationary in front of the body, slightly shifting its thumb and fingers to maintain its grip.
Deliver

Annotations as JSON, per segment.

Every segment ships with its hand, label, start and end time and caption, ready for training.

See the delivery format
# s8-segment.json · excerpt
{
  "clip": "S8",
  "track": "right_hand",
  "label": "Grasp",
  "primitive": "grasp",
  "start": 427.079,
  "end": 430.876,
  "text": "The hand holds the component…"
}

Start with a free sample.

Pulled from the Video Datalake. For partnerships, pricing, support or press, use the same form and our team will get back to you.

We work with the best of the best pushing the frontier of physical AI.
What are you interested in?
or email us directly:
[email protected]
Thank you for the information
A member from our team will be in touch shortly.
Oops! Something went wrong while submitting the form.