Real work, everywhere.
Our own rigs record at real work sites: a head-mounted stereo pair and a wrist view, synced.

We run the end-to-end system that enables efficient training cycles.
Wearable rigs record video where the work happens, mounted at the head, wrist, chest, cap or neck. Also captured: raw IMU and camera calibration.
Each hand's actions become time-stamped segments, so the lake can be searched by action.
ExploreWe query the lake for the video you need, then annotate it against your taxonomy.
Read the API docs# retrieve.py · illustrative
moments = lake.retrieve(
venue="construction site",
scenes=["rebar area",
"formwork area"],
skill_level="hard",
where="both hands on the tool",
exclude=["hand idle", "walking"],
)
moments.annotate(
taxonomy="your_taxonomy.yaml")
# → rebar and formwork moments, labelledEach hand gets a caption for every segment, written against your taxonomy frame by frame.
Explore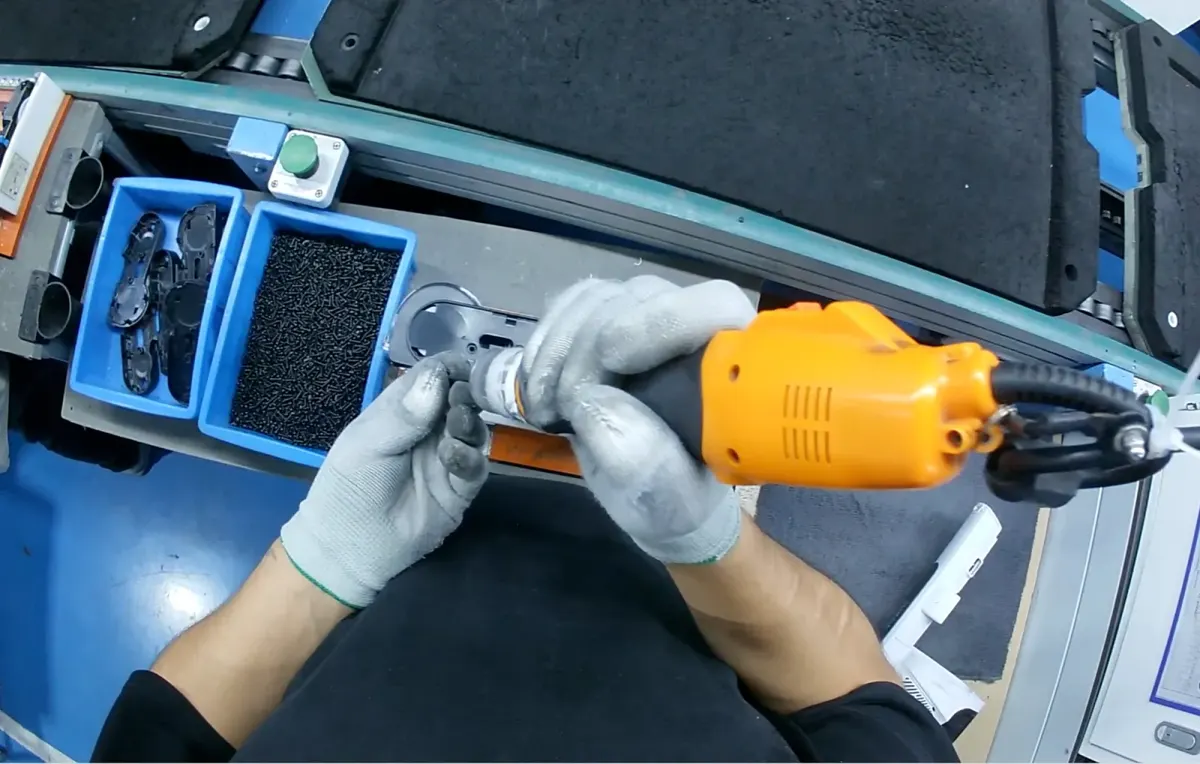
Every segment ships with its hand, label, start and end time and caption, ready for training.
See the delivery format# s8-segment.json · excerpt
{
"clip": "S8",
"track": "right_hand",
"label": "Grasp",
"primitive": "grasp",
"start": 427.079,
"end": 430.876,
"text": "The hand holds the component…"
}Egocentric data from our lake.
Indexing and dense annotation on your own video.
The models and infra to train on it.